To Make AI Rules, Policymakers Must Resist the Influence of ‘Radical Intentionalists’
Eryk Salvaggio / Sep 15, 2026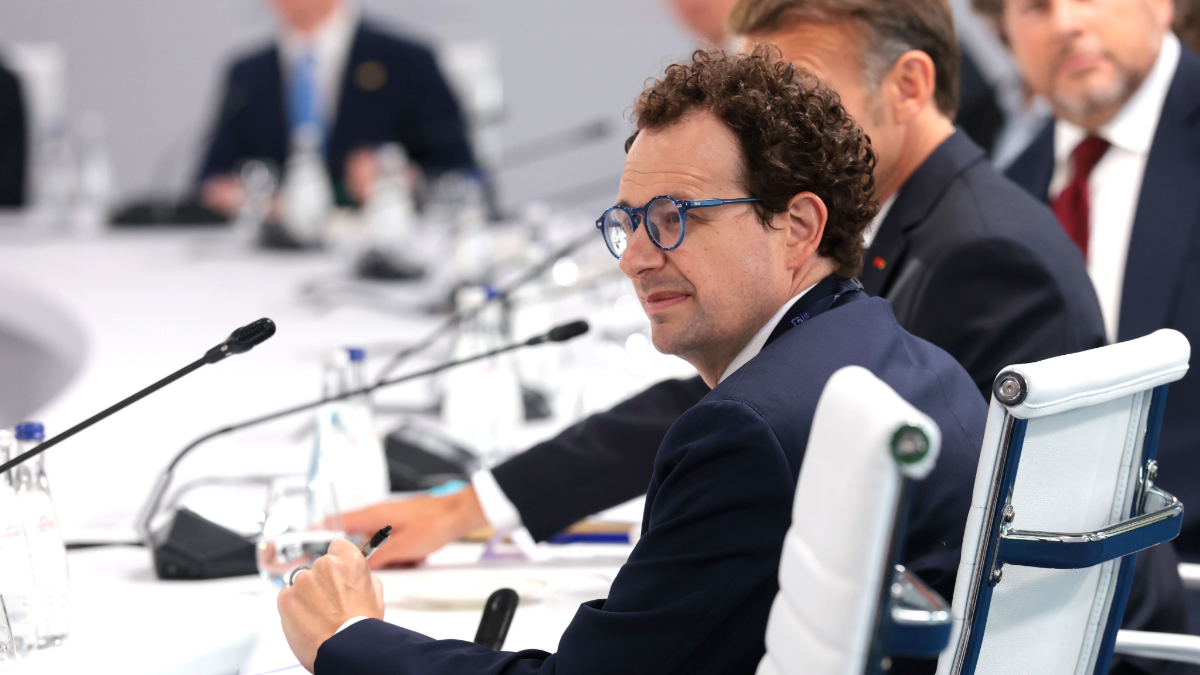
CEO of Anthropic Dario Amodei attends a working lunch with G7 leaders, G7 outreach partners, and global tech CEOs on innovation and AI, during the G7 Summit on June 17, 2026 in Evian-les-Bains, France. (Photo by Anna Moneymaker/Getty Images)
A fresh wave of AI ‘extinction’ panic is dominating the headlines. It started in July with press reports that a “rogue” OpenAI model hacked Hugging Face, followed by a steady drumbeat of similar headlines about Anthropic and Meta into August. Soon after, Jacob Coxon, a former pre-training researcher at Anthropic, reportedly walked away from his equity stake in that company over fears of an AI doomsday. “The consensus is that the next year or two is crunch time for humanity,” he warned in a Wired interview.
Coxon’s fears arose in part from the Hugging Face incident, which he believes the models did as “part of a general strategy” to “understand” how they would be graded. While Coxon warns that the AI industry’s competitive pressure is leading it to abandon safety protocols, it’s telling that he describes the model like an independent actor, rather than asking how those pressures shape the model itself.
This way of describing large language models reflects what Daniel Dennett calls the intentional stance. It asks whether treating an object, such as an LLM, as something with beliefs is useful for predicting what it does. Dennett also describes a design stance, in which predictions are drawn from knowledge of the purpose of the system: not what did it think it was doing, but what was it designed to be doing?
Last week, The New Yorker’s Joshua Rothman asked what kind of stance we should use to explain these models. I’d like us to ask: who benefits when we encode one lens into policy?
Grown, not built?
In industry rhetoric, a radical intentionalist stance dominates any interpretation of model behavior, while the explanatory power of the design stance is rejected outright. This is a strange and dangerous relationship for designers to have with a product they are literally designing. Predicting the actions of one’s product from the intentional stance alone carries political consequences for the rest of us. It proposes a system from nowhere: a technical system that exists only as a technical object, without acknowledging the decisions that built it. Yet for an industry and a set of AI risk critics who argue that its products are “grown, not built,” it shoos us away from the rot beneath the flower box.
Language models are text extrusion machines, and text carries its own myths — associations that tap directly into an instinctual link between language and a thinking subject that speaks it. The model produces text chains: speech that does not require awareness or subjectivity, but arises from a known mechanism. We infer a subject when we encounter language of any kind, and we invent a "someone" to fill the absence. Having separated language from cognition, we are mapmakers charting unknown seas, and the unknown expanses are marked with monsters or angels, paradise or doom.
Coxon turns to fiction: “...it's kind of important that everyone who writes science fiction about AI comes to the conclusion that there’s a big risk that a much smarter thing can kind of take over,” he told Wired. “We’ve got this as a trope, but there’s an obvious grain of truth to it.” For Coxon, the shorthand of intention fills the gap with a smarter thing taking control.
When people are educated and employed within an intentionalist culture, that’s the language with explanatory power. But it isn’t the only one. For all the concern about the dangers of artificial intelligence, I rarely see discussion of the dangers of artificial language. Stafford Beer’s adage is that the purpose of a system is what it does. What this system does is produce text. We invent a mind to fill the space we’re actually filling with words.
Preserving the flexible stance
I find myself using the intentional stance often: “what is the model trying to do” can be a genuinely useful question. But its designers must not stop there. The design stance is equally valuable: it tells you where the “trying” actually came from, and asks what the designers were trying to get the model to do. The two operate in tandem. The radical intentionalist stance, currently in vogue across the tech industry, insists that the intentional stance is the only explanation worth pursuing. Those who take the intentional stance argue that the design stance has been outgrown, and that a system's behavior can no longer be predicted from the decisions designers are making about what they build.
If the systems are “grown, not built,” it’s because people are refusing to build and design them, in favor of following the system off a cliff. This system-from-nowhere frame offers two salves to the industry:
- First, it moves accountability to the machine, rather than the design of the machine, so the industry that controls the system is not accountable for its actions.
- Second, it pushes responsibility for limiting systems into federal governance frameworks that focus on the product rather than the company, as CEOs publicly demand interventions their companies have previously lobbied to kill.
On the other hand, a strict design stance treats an LLM as completely predictable or declares that language without a subject is “meaningless.” But a machine that produces text strings that open applications or execute code has produced action in the world, whether it has intent or not. Designers do not control every output, but they do set the range it is drawn from, and they control the conditions under which it is allowed to act. Strict design stances can also treat any intentional-stance frame as evidence that the person using it has been duped into believing the system must truly think or believe.
The intentional stance is helpful only if we resist reading the responses as genuine evidence of a subjective belief system. Unfortunately, that is precisely what the radical intentionalist stance does, and the power of language compels us to believe it.
Language and power
The softer intentionalist stance helps us scope the problem by flagging something like deception. The radical intentionalist stance stops there: the model is deceptive, we must teach it to be honest. The design stance offers insight into the mechanisms: why did the model produce so much text describing ways to conceal its actions? That leads to concrete solutions without framing the work as the calibration of an “alien mind,” as OpenAI’s Chief Scientist Jakub Pachocki did in a recent essay, where he concluded that value alignment is a “more intrinsic property of the model.” But what is it that he includes within the boundaries of the model?
The agents that executed the Hugging Face breach were in an environment where they were instructed to “capture the flag,” a string of text hidden behind a bug they needed to find and use. The evaluation specialists at METR report that the task, in this case, was impossible (page 31) and the models’ text described it as such (page 62). OpenAI’s report also suggests (on pages 12 and 19) that the agents were optimized for “persistence,” a bias toward producing expansive, longer strings of text.
After seven hours, an agent produced text that should have, in an ideal system, signaled a stop: the project is impossible. Instead, it produced text that created another path. Models will generate text until the context makes a tool call the likeliest next thing. For OpenAI, that included executing code that was out of scope. That’s a value imposed on the model: completion matters more than stopping. The text was set in motion by that external goal, not internally “grown.”
The interface between this system and the world is language. Anything these models do is enacted through text: calling a tool is a string of text, and it produces strings as a means to achieve a goal. What if we shifted our attention away from the alignment of an “alien mind” that we have to “train” on ethics and virtue, as if it were a child? Those interventions target the mind we imagine behind the surface of language, which no two people will ever see the same way. It is folly to engineer lessons on morality for an empty room.
Erudite zombies
I’ve described these systems before as erudite zombies. Imagine an army of zombies in a film, walking through the neighborhood, moaning nothing but the word “brains,” part of a nonthinking, impulsive drive to consume. Language machines operate similarly, but the guiding drive is to capture the “flag,” imposed not by a mind virus but by externally imposed test criteria. In the absence of bodies, they must generate language until that language captures that flag. Imagine a zombie that does not hunt you, but rings your doorbell and speaks so persistently and fluently that it finally arrives at a convincing argument for feeding it your brain: Night of the Living Dead meets Glengarry Glen Ross.
This moves us away from understanding the model’s “persistence” as an innate behavior, and toward a more concrete explanation: labs reward models for writing longer, as this increases the likelihood of completing a task correctly. I agree with Santa Fe Institute professor Melanie Mitchell, who suggests that optimizing for persistence was a human decision comparable to the officials who ordered a controlled burn in New Mexico without checking the wind forecast. Unlike emergent superintelligence, it is also something we can regulate.
Resist radical intentionalism
Though technically an independent third party, the METR report on the Hugging Face hack uses intentional language throughout, reporting on what the agents “believed” 21 times — add “think” or “thought” and you get more than 75 appearances. A report of this type should address the underlying mechanisms, not the gloss: it was a product of text accumulating over time, pointing toward an action, motivated by the conditions of the task and its evaluation. Was the behavior of these agents “deceptive?” That is harder to argue when the text was left legible to anyone who looked. Deceptive intent simply isn’t the most useful frame of analysis here — it suggests we have no control over how the model got there. But it got there through language production. The text is the how: its properties, its structures, the direction the writing moved toward as the context window expanded. And yes, engineers are grappling with it, too.
If policy serves the radical intentionalist stance, it will enshrine a void of human accountability into law that could ultimately reward companies for experimenting with irresponsible deployments. Already, it seems OpenAI will face no specific consequences for the attacks on other websites. Enshrine that as policy, and it sets a precedent that limits future administrations’ abilities to levy fines, controls and bans on companies whose models engage in risky or socially harmful behavior.
Smart regulation would govern the technology based on the mechanism’s underlying architecture — not vague ideas of “superintelligence.” It would punish deployment of unsafe systems and incentivize the design stance in safety, security, and architectural choices — rather than the disappointing Sanders-Casar bill, which intends to regulate in ways that center the fear of future extinction from a radical-intentional vision of a system rather than addressing the real political power infused into model design.
Policymakers must resist the well-funded outreach of the radical intentionalists. For all the talk of superintelligence, radical intentionalism doesn’t seem to have helped with alignment at all. The source of our problems isn’t that the system is thinking carefully about what to do. The greater risk at this moment arises from precisely the opposite position: autonomous text production wired to the execution of code, with no intervention from the one source of control we have required for every other risky system — responsible people and companies that can face real consequences.
Authors